
Automation exception handling: what happens when the workflow cannot finish?
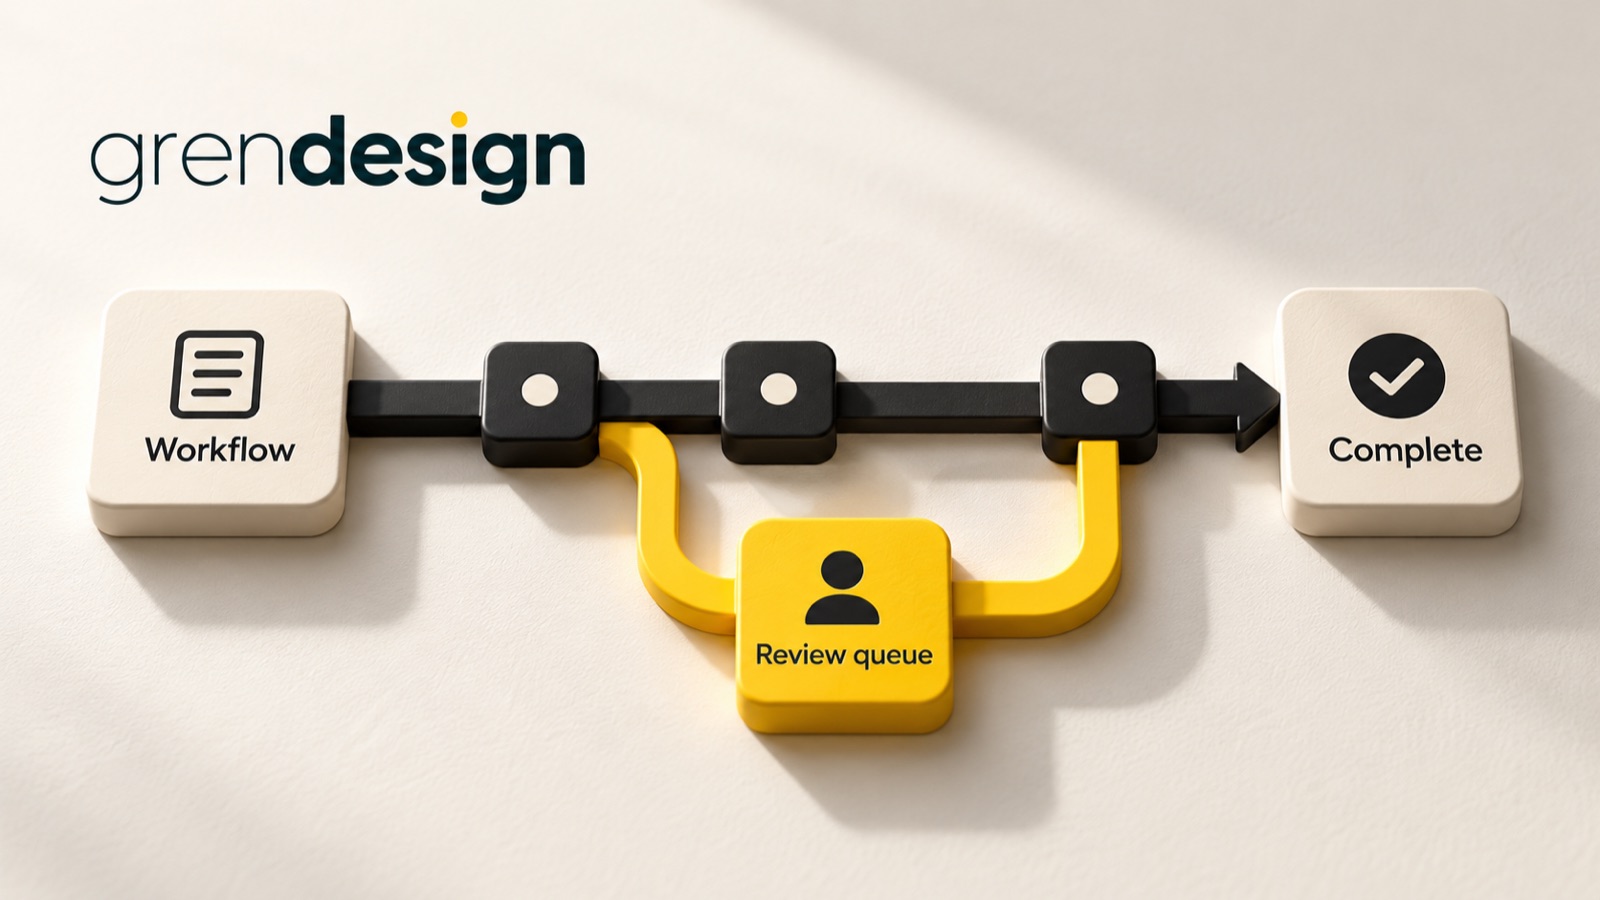
An automation needs a plan for the work it cannot finish. Define how it recognises a problem, preserves the original request, avoids duplicate actions and gives a person enough context to take over. That plan is part of the workflow, not an optional repair service.
Put the advice into practice
Build a workflow your team can actually rely on
Connect systems and follow-up with agreed rules, human review and exception handling.
Discuss your workflowWrite down what complete means
Consider a website enquiry that creates a CRM record, assigns a salesperson and sends an acknowledgement. Which of those steps must succeed before the workflow is complete? If the record exists but nobody owns it, the technology has moved data without finishing the business job.
Describe the final state in terms a team member can check. For example: the enquiry is stored once, linked to the correct contact, assigned to an available owner and visible in the follow-up queue. Keep customer communication as a separately tracked action.
Then describe partial states. A record created without an owner is different from a request that never reached the CRM. Knowing the difference helps the team recover only the missing work rather than repeating the entire chain.
Separate temporary failures from decisions a person must make
Not every exception should trigger another attempt. A brief service interruption may be temporary. A missing mandatory field will not repair itself. A permission failure may need an administrator. Two plausible customer matches may require a human judgement.
- Temporary technical problem: a connection times out or a service asks the integration to slow down.
- Invalid input: a required value is absent or in an unsupported format.
- Business exception: the request is legitimate but falls outside the normal rule.
- Permission problem: the connection no longer has the necessary access.
- Uncertain outcome: the request may have succeeded, but the confirmation did not arrive.
For each category, choose a response. A bounded retry can suit some temporary problems. Invalid input needs correction. An uncertain outcome needs a status check before another consequential action. Give unknown error types a safe default instead of letting them disappear.
Make retries safe before enabling them
Imagine an integration creates an appointment, then loses the response. Retrying the entire workflow could create a second appointment. The absence of a success message does not establish that nothing happened.
A common technical safeguard is idempotency: identifying repeated attempts as the same intended operation. Stripe’s API documentation provides a concrete example of idempotency keys for safely retrying requests. Other services have their own rules and limits, so ask your developer what the actual destination supports.
For a business brief, the important questions are straightforward. How is the original request identified? How does the system check whether an action already happened? Which steps can safely be repeated? What happens when the destination cannot answer?
Do not assume a contact duplicate check protects every later action. One contact record can still receive two emails, two tasks or two bookings. Each consequential step needs appropriate duplicate protection or a controlled review route.
Build a queue that someone can actually work
An exception queue is a list of unresolved work with ownership. It should make the next action clear without forcing staff to interpret a long technical log.
Include the original request reference, the stage reached, a plain-language reason, the time first affected, the next action and the responsible person or role. Link to detailed diagnostics for the person who needs them, rather than copying sensitive payloads into a broad email alert.
Separate urgency from the order in which errors arrived. A failed internal summary and a customer waiting for a promised callback should not necessarily receive the same priority. Agree priority rules with the people responsible for delivery.
Give each item a status such as awaiting review, awaiting customer detail, retry scheduled or resolved. Record the resolution. Closing an alert should mean the business problem was addressed, not merely that somebody read the message.
Nominate cover for leave and absence. “Notify the owner” is only a complete instruction when the owner is available or there is a fallback.
Keep customer messages accurate during failures
A confirmation message should describe what the system knows. “We’ve received your request” can be appropriate after reliable receipt. “Your booking is confirmed” needs evidence that the booking actually exists in the authoritative system.
Draft failure and delay messages before launch. They should explain what happens next without exposing technical details or making promises the team cannot meet. Keep unnecessary promotional content out of operational messages.
In an illustrative workflow, the website stores an enquiry successfully while the CRM is unavailable. The customer receives an accurate receipt acknowledgement. The request enters a controlled recovery queue, and an assigned person can see that CRM routing is still pending. This is preferable to either losing the request or telling the customer a salesperson has already been assigned.
The exact arrangement depends on your platform, security requirements and service commitments. The principle is to keep receipt, processing and completion separate in both the workflow and the language.
Rehearse recovery with the people who will do it
Use a test environment and fictional records to interrupt the workflow at different stages. Try an unavailable destination, an expired connection, duplicate input and a late response. Ask the nominated owner to recover each case using only the information the system provides.
If recovery requires knowledge held by the original builder, improve the instructions or support arrangement before launch. A practical runbook should identify how to inspect the destination, when a retry is allowed and who can authorise a manual correction.
Test the pause control too. During a widespread issue, continuing to create new failed work can make recovery harder. Decide whether to pause the entire process, only the affected branch or only actions that change customer records.
After a repair, reconcile the queue against the destination. A successful test does not prove that every earlier request was recovered. Close the incident when the outstanding work is accounted for and customers have received any necessary follow-up.
Measure unresolved work, not just successful runs
Track the oldest unresolved item, the number awaiting a person, repeated failure causes and the time spent recovering. These measures help distinguish a rare exception from a process that regularly transfers hidden work to staff.
Use patterns to improve the original workflow. Repeated missing information may call for a better form. Repeated ambiguous routing may call for clearer ownership rules. Adding more retries will not solve either problem.
When discussing AI and automation with Grendesign, include the exception route in the brief alongside the normal sequence. Ask to see what happens when a step fails, who notices and how the request reaches a verified end state.